Interactive Parallel Quadtree Construction
The purpose of this post is to interactively demonstrate the construction of a quadtree structure using purely parallel methods. This is largely based on the classic Karras 2012 paper. I’ve modified it slightly to accommodate a particular quadtree data format which works well for fast top-down traversal, with the application in mind of an n-body simulation.
This is a tool to visualize the structural and memory layout of the quadtree that results from the tree construction process.
The Tool
Click on cells in the grid below to mark them as occupied or unoccupied. A quadtree structure will be generated around the occupied cells. This widget supports up to 10 particles, so if you add an 11th, the oldest particle will be removed and all indices will be updated.
The following diagram illustrates the structure of the quadtree which stores the hierarchy of bounds in the spatial grid above. Each node contains a triad of indices: (parent, child, next). Click on a node to highlight its relationship to other nodes, or click on a leaf-data payload element to see how traversal through the tree would look in order to reach that element.
The tree/index order toggle reorders nodes to show the hierarchical structure or the actual order in which the nodes of the tree are stored in memory.
This article, the algorithm it describes, and the C++ implementation are all still a work in progress.
Changes to the occupied cells using this widget will be reflected in the memory diagrams throughout this article, illustrating how buffers are populated at every step of the construction of a quadtree. Crucially, each step of this algorithm can be executed in parallel. Some of them lend themselves well to the use of SIMD primitives, but any of them can be done using SIMT (i.e., GPU kernels).
In Karras’ paper, the octree construction phase is packed into two paragraphs. In order to really understand the entire tree construction process - from Morton encoding to radix tree construction and building the final octree - I found myself writing up many 8x8 plots of points in order to think through edge cases on paper.
My hope is that this tool will help the reader (and myself!) to think through the fast, parallel tree construction process in a more intuitive, visual way. This article does not claim to explain each step in algorithmic detail (although you can inspect the javascript if you wish! I warn you, it’s a little messy). Instead it describes each stage in English, and illustrates its results.
The Explanation
Step 0: Morton Encoding
The square in the first chart above is a region of space, sparsely populated by particles in any order. Each cell is a point in space which is most finely representable given a certain number of bits. In this case we limit ourselves to just 3 bits for simplicity, so the x and y coordinates are each integers in the range $[0,8)$.
The array containing particle positions is our input vector. For each entry, a Morton key will be generated by interleaving the bits of the binary representation for the $x$ and $y$ coordinates.
This process is trivially parallel and has complexity $O(N)$ in the number of particles.
Step 1: Morton Key Sort
Sorting an array of Morton keys puts them into an order where spatial proximity correlates with proximity in address space. Because we may also have data other than positions associated with leaf nodes, we will simultaneously produce a reverse map - an array of indices back into the original particle positions array.
A Radix Sort can be used here, which is also $O(N)$.
Step 2: Radix Tree Construction
Each of the $N$ Morton keys is a leaf node in a radix tree which has $N-1$ internal nodes. Each internal node in a radix tree represents a splitting index - given a range of keys which share a common prefix, the splitting point for that range is the point at which the next most significant bit past the common prefix begins to differ. For example, if you have a range containing the keys 0:110001, 1:110010, and 2:111001, the common prefix is 11 and the splitting point would be between elements 1 and 2 because that is where the bit just past the prefix changes from 0 to 1.
The node splitting pattern is illustrated in the following diagram. The first row shows the leaf nodes of the radix tree - i.e. the sorted Morton keys from the diagram above. The subsequent rows show the prefixes, ranges, and split positions for each of the internal radix tree nodes.
The following arrays are the radix node data, which will be fed into the next step for construction of the quadtree structure. Internal node indices are prefixed with an *. Other indices refer to leaves (the sorted Morton key array).
The quad_internals and quad_leaves values indicate the number of internal and leaf quadtree nodes that will be emitted by each radix node. Karras uses only the first of these two numbers, but I’ll need the second as well for the linear quadtree format that I’ll construct in the final step.
It’s possible that for some applications the parents array is not actually necessary. However, for a Barnes-Hut implementation a bottom-up traversal of the tree is needed in order to accumulate mass data from child nodes. Parent indices are needed for bottom-up traversal.
Step 3: Quadtree Allocation
The number of nodes in the quadtree that we will produce does not have a simple relationship to the number of radix nodes or keys, unlike every other buffer described up to this point. From the quad_internals and quad_leaves arrays, we know how many quadtree nodes to allocate for each radix tree node. To get the total, we first compute the sum quad_internals + quad_leaves, and then the exclusive prefix sum on the result.
The entries of the resulting buffer will be the offsets into the quadtree node array for each radix node. The last value (plus one, for the root node) will indicate the total number of quadtree nodes to allocate.
Step 4: Create Leaf Node Map
This is an intermediate step to create an index map from the leaves/keys array into the quadtree nodes array. Each key corresponds to a leaf node in the quadtree. It’s necessary to keep these indices around so that leaf nodes can be inserted into the correct locations in the final quadtree structure. It is also useful for bottom-up traversals of the tree starting with the leaf nodes, as we will need to do for Barnes-Hut.
Step 5: Construct Quadtree/Octree
The quadtree nodes themselves. The array is as long as the total from step 3, and each node holds the index of its parent, its first child, and the “escape index”, next. next carries two meanings - in the case that a node has a sibling that follows it, next will be the index of that sibling. Otherwise, if the node is the last child of its parent, next will equal its parent’s next.
next is referred to as the escape index because a node’s next is used to escape a branch of the tree when a traversal decides not to go any deeper. For example when a node’s mass approximation is “good enough” in a Barnes-Hut implementation, the next pointer can be used to jump to the next branch and skip the whole subtree.
This brings us to the quadtree widget which opened the article - here it is again, to save you a trip to the top of the page:
If you select a leaf data cell, and switch to “index order”, it is quite obvious in many cases that memory is not traversed in order. For trees that do happen to be in depth-first search (DFS) order, a traversal through the tree in the index order view should look like an arrow hopping from left to right and down, in a cache-friendly way.
Each Morton key contains enough information to reconstruct the bounds of each node of the quadtree, down to the corresponding leaf. For intermediate nodes, a subset of the bits of the Morton key are needed. For a quadtree, each pair of bits corresponds to a bounds. The most significant two bits will be the outermost bounds, and the least significant two bits will be the innermost bounds - every pair of bits in between is a level in the quadtree. The first bit in a pair is the x-axis, in our case - zero means left half, one means right half. The second bit indicates bottom or top. Every pair of bits is the subdivision of the previous pair’s bounds.
These node bounds are not shown in the memory diagram above, but they’re computed and stored in the quadtree nodes during the quadtree construction of step 5, alongside the parent, next, and child indices.
Finally, we’ve produced the quadtree of bounds that was rendered at the top of this article. Each internal node is split into its four quadrants, and each leaf is outlined with a dashed line. Particles are indicated by their circled indices into the original particle array.
There are many subtleties in the implementation of this algorithm which aren’t covered here, but every step of this quadtree construction can be easily generalized to three dimensions, and can be executed in parallel. Tree construction performance approximately doubled in comparison to serial tree construction.
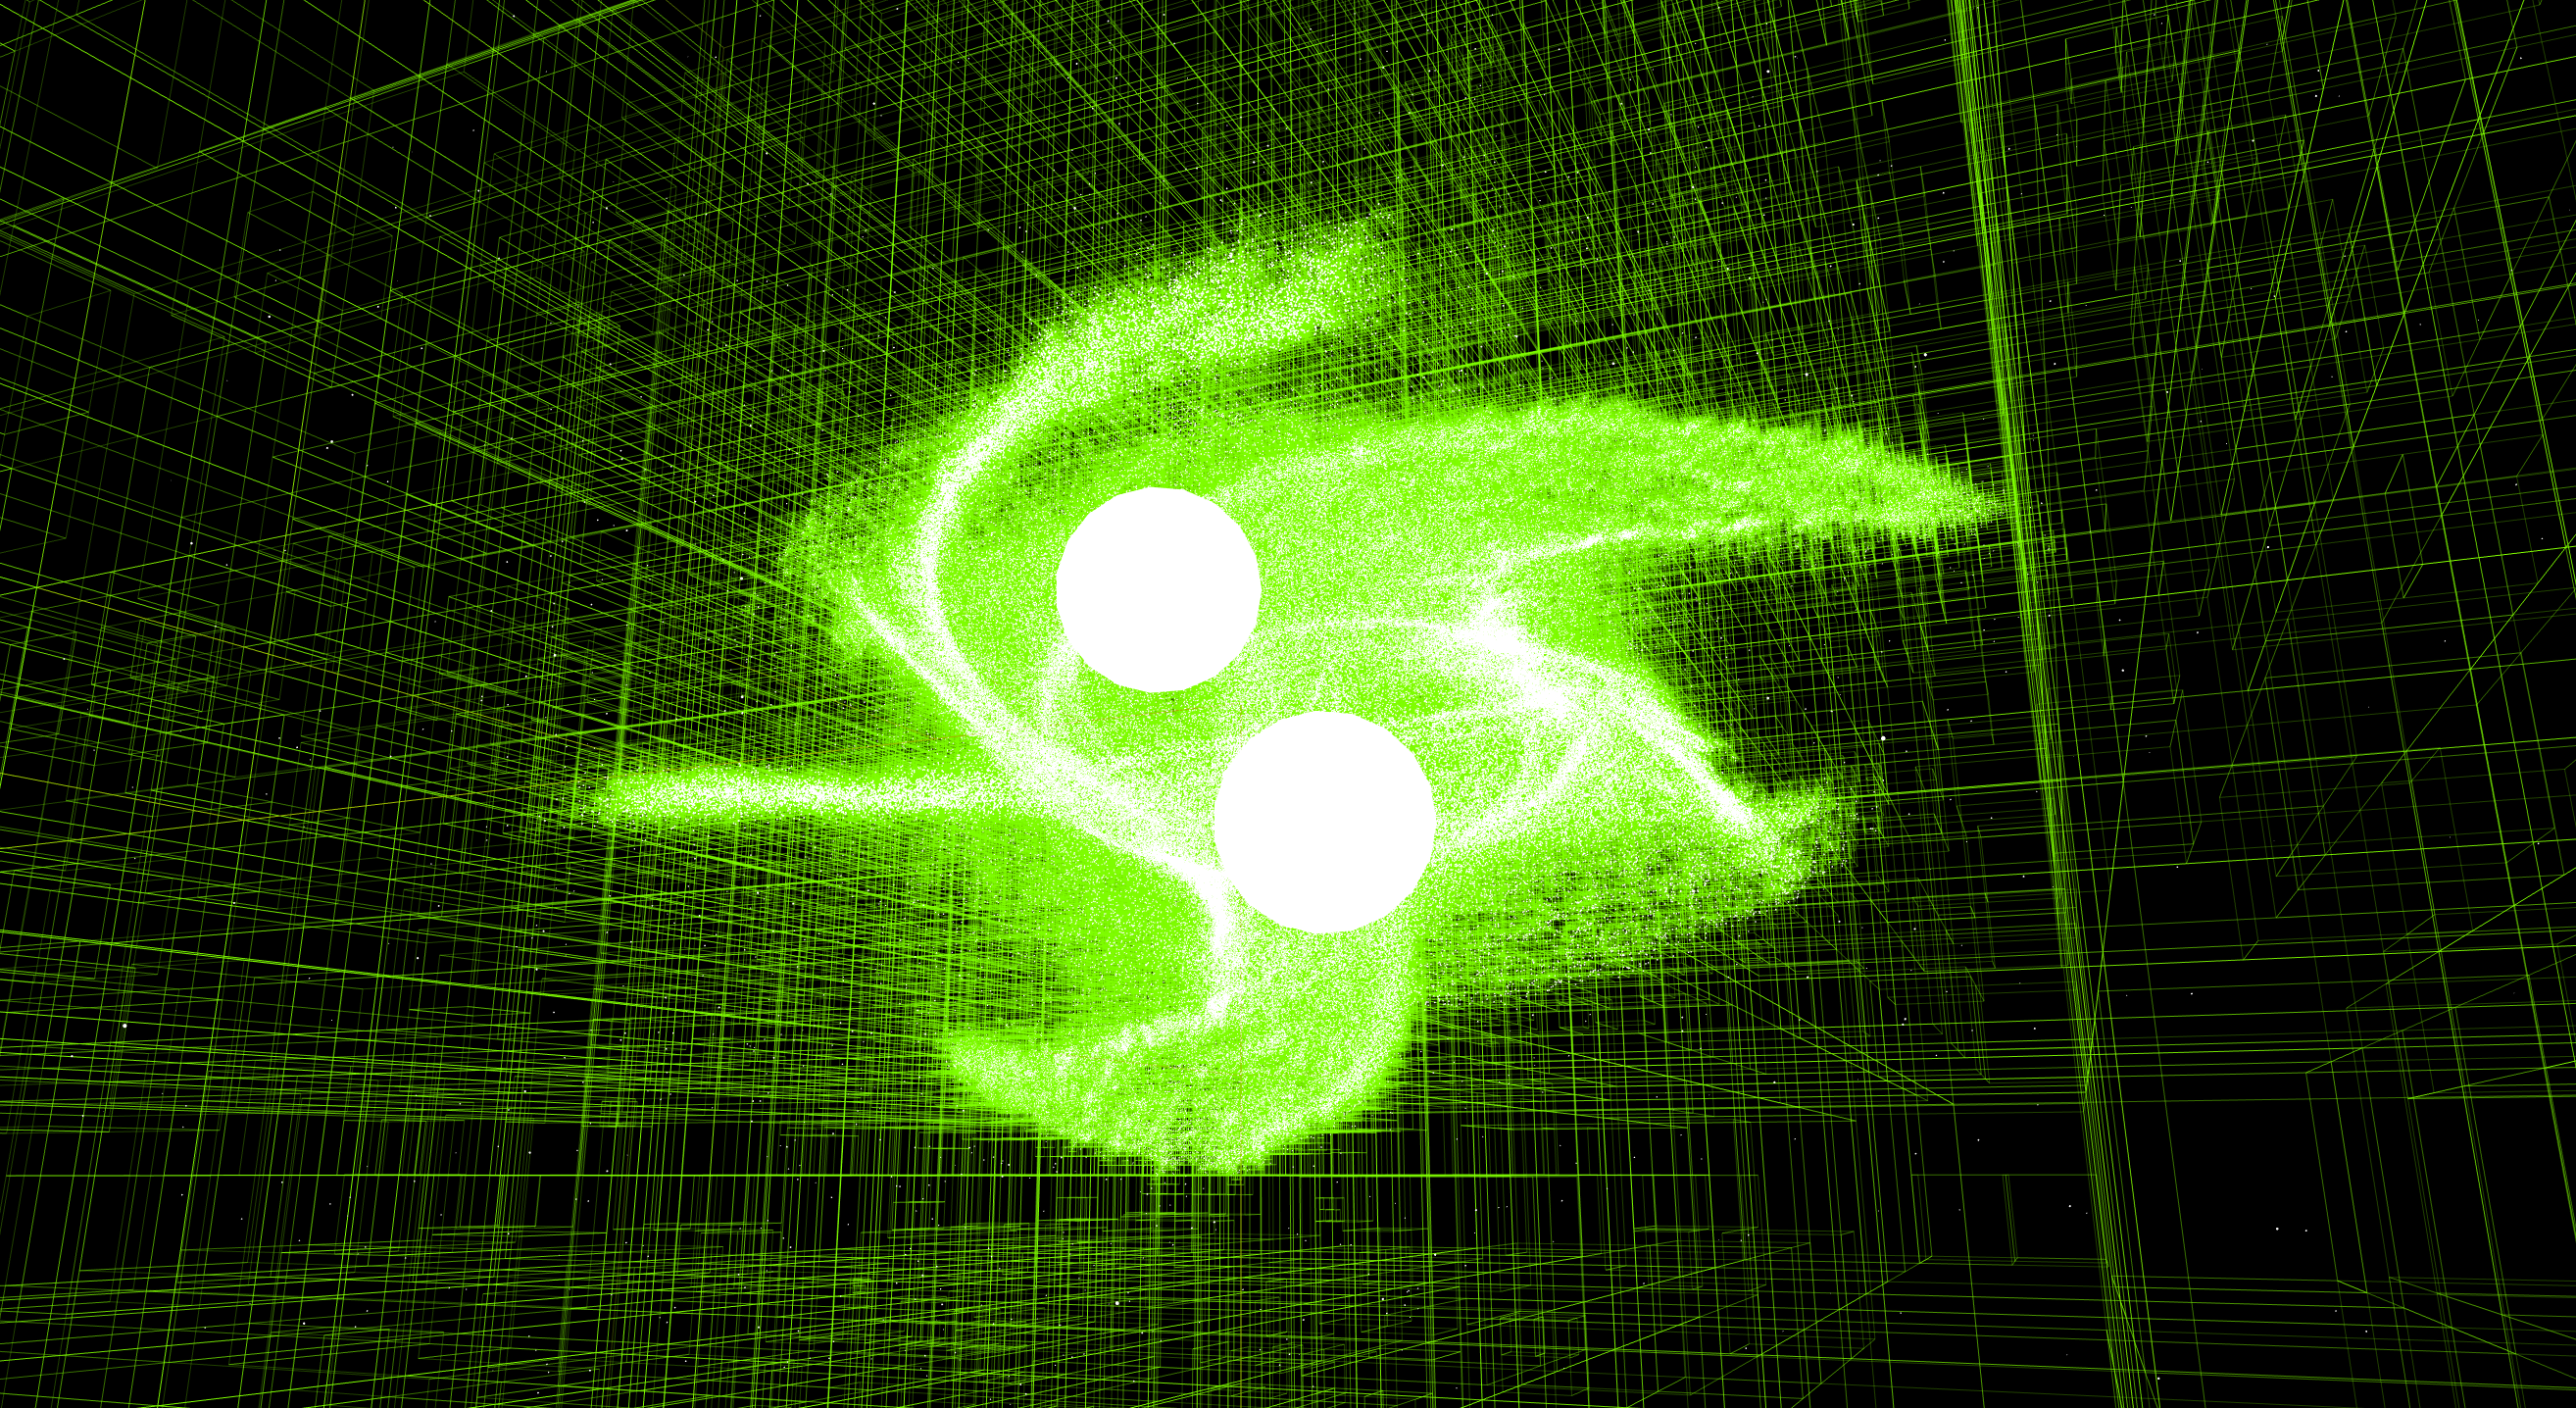
The following image is the octree containing all of the stars in the colliding-galaxy simulation from the video at the top of the article.
Final Notes
This algorithm is not fully complete yet - as can be seen from the index/tree orderings in the final construction of the quadtree, the escape-pointer quadtree structure is not optimal. A regular traversal can cause cache misses because the nodes are not sorted into depth-first-search (DFS) order, which is the order that this structure typically benefits the most from.
While building the n-body simulation, I’ve gone through many iterations and compared profiles. Putting the tree construction into this form benefits massively from parallelization and use of SIMD, but the cost of traversal increases significantly due to the loss of DFS ordering in the final structure.
Besides just optimization of memory access, DFS ordering of the quadtree/octree could potentially allow removal of the parent and child indices since the first child of a node would always immediately follow its parent in memory. A bottom-up traversal would be a scan from right to left, and a top-down traversal would be a scan from left to right. This would be a significant savings in memory usage, while further improving cache friendliness.
I’m currently exploring adding another parallel sort step into this algorithm that will produce a DFS-ordered structure, which would enable these optimizations. Careful profiling and attention to memory layout are essential to check my assumptions on how the changes I described will actually affect performance.
In the meantime, building these diagrams has helped me understand these algorithms and visualize the memory layout of the radix tree and quadtree data structures. Hopefully if you’ve stumbled upon this page after reading Karras, you’ve found these visualizations a helpful supplement.